Go back

// article

Adventures in LoRA Training

training a thing is... fun

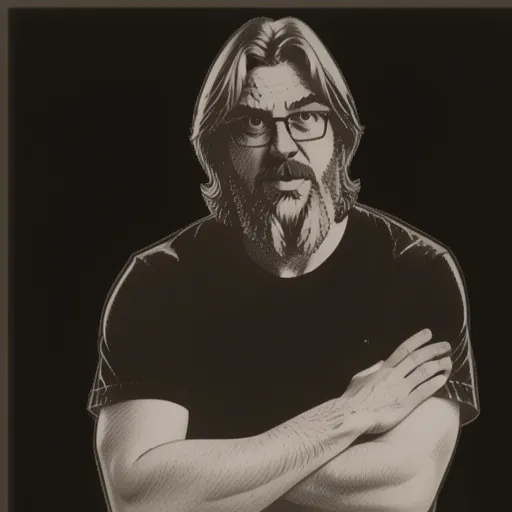
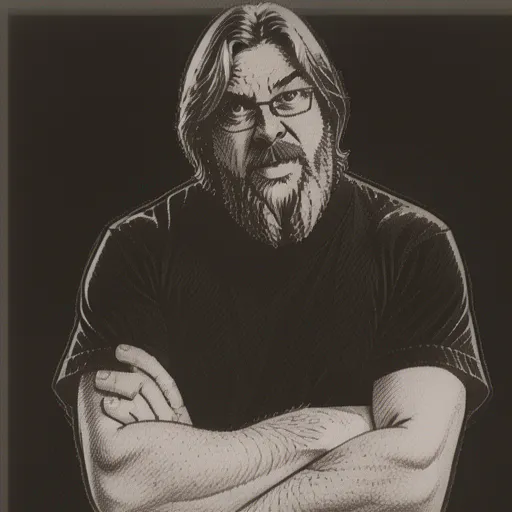
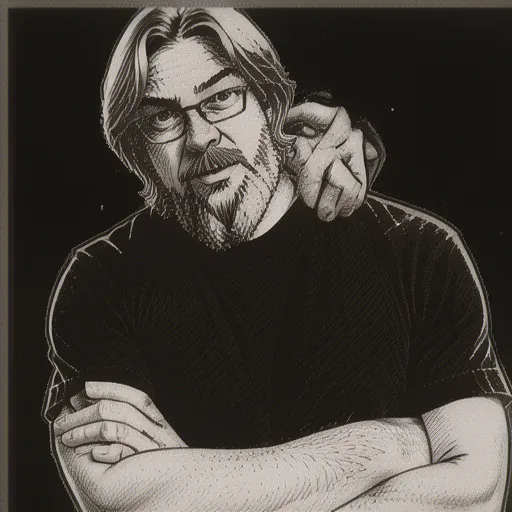
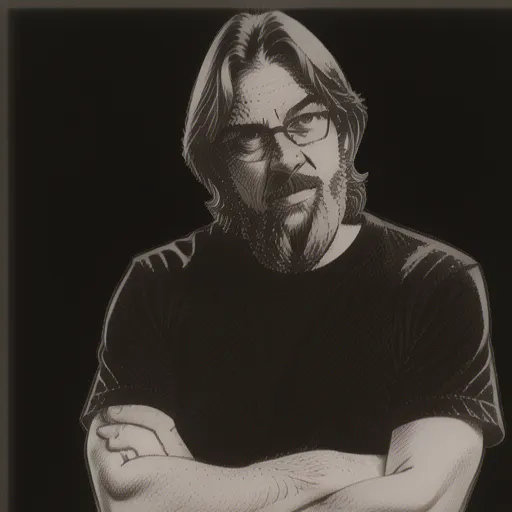
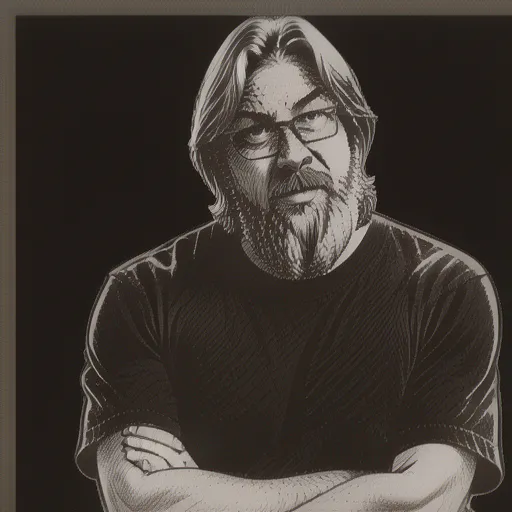
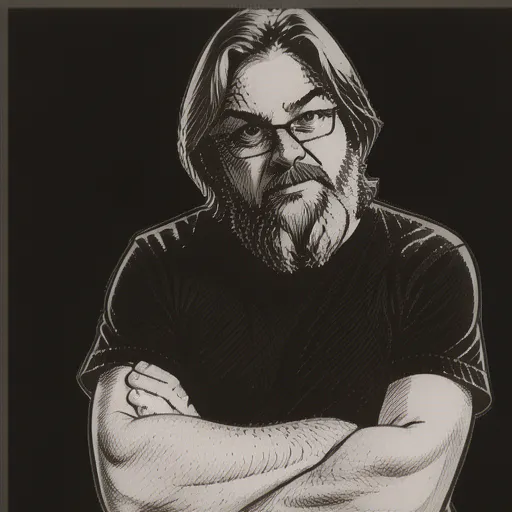
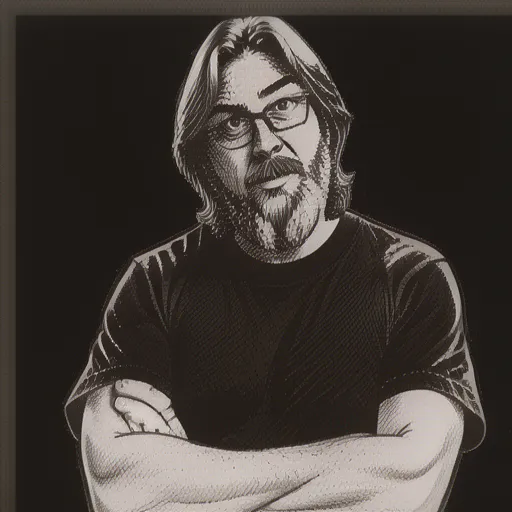
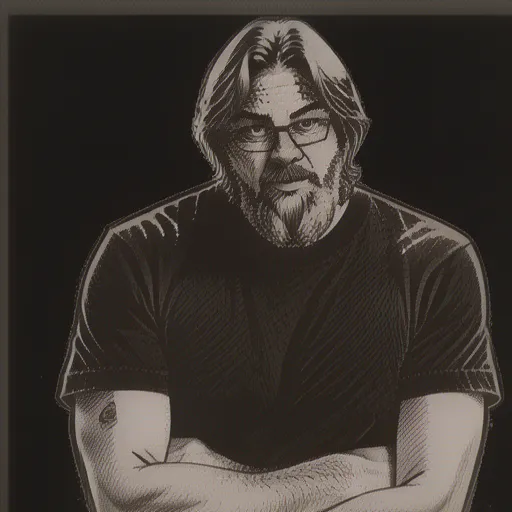
I have been playing with training a Flux LoRA model locally on a M3 Pro 36GB Macbook. The results have been really good, but the mistakes are too weird to delete.

model:
name: klein-4b
quantization: bf16
lora:
rank: 64
alpha: 64.0
target_layers: attention
training:
batch_size: 1
max_steps: 1500
warmup_steps: 25
learning_rate: 1.0e-4
weight_decay: 0.0001

After a few more local experiments to find the sweet spot between dataset and settings I’ll put this into a job on huggingface with 9B and a CUDA-native process with ai-toolkit and a single 48 GB L40S (--flavor l40sx1).
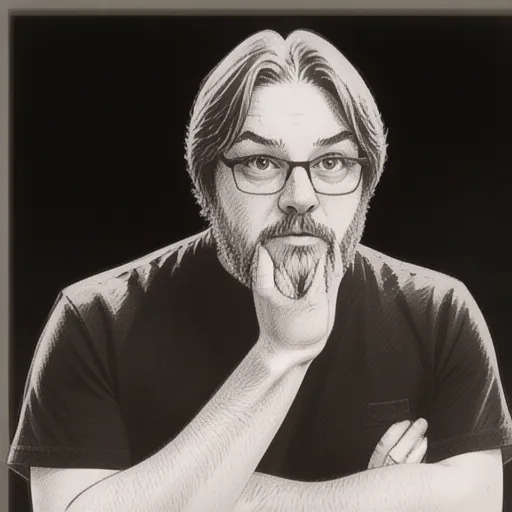
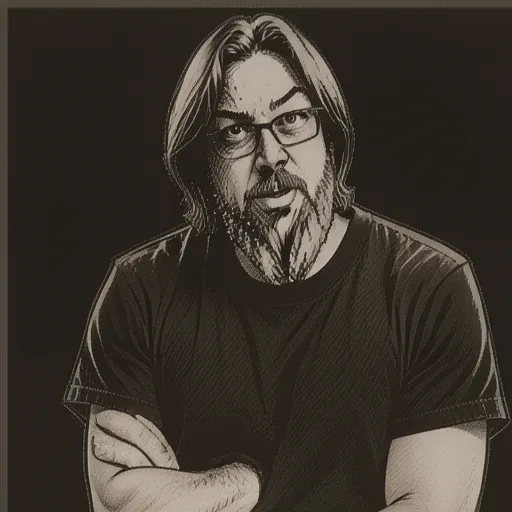
checkpoint: 125, scale: 2

checkpoint: 000125 scale: 2

checkpoint: 000250, scale: 2

checkpoint: 000250 scale: 2

checkpoint: 000375, scale: 2

checkpoint: 000375 scale: 2

checkpoint: 000500, scale: 2

checkpoint: 000500 scale: 2

checkpoint: 000625, scale: 2

checkpoint: 000625 scale: 2

checkpoint: 000750, scale: 2

checkpoint: 000750 scale: 2

checkpoint: 000875, scale: 2

checkpoint: 000875 scale: 2

checkpoint: 001000, scale: 2

checkpoint: 001000 scale: 2

checkpoint: 001125, scale: 2

checkpoint: 001125 scale: 2

checkpoint: 001250, scale: 2

checkpoint: 001250 scale: 2

checkpoint: 001375, scale: 2

checkpoint: 001375 scale: 2

checkpoint: 001500, scale: 2

checkpoint: 001500 scale: 2


Share this post on:

Previous
JEV: The Unusual AI Model I Think Could Be Really Useful in Real Applications
Next
MLX Engine Benchmark Showdown